Anthropic updated its models — Fable 5.1 has been released, while the Mythos 5.1 version with softer safety filters was rolled out for closed testing. The model has been trained to work much better with code, browsers, and complex chains of actions.
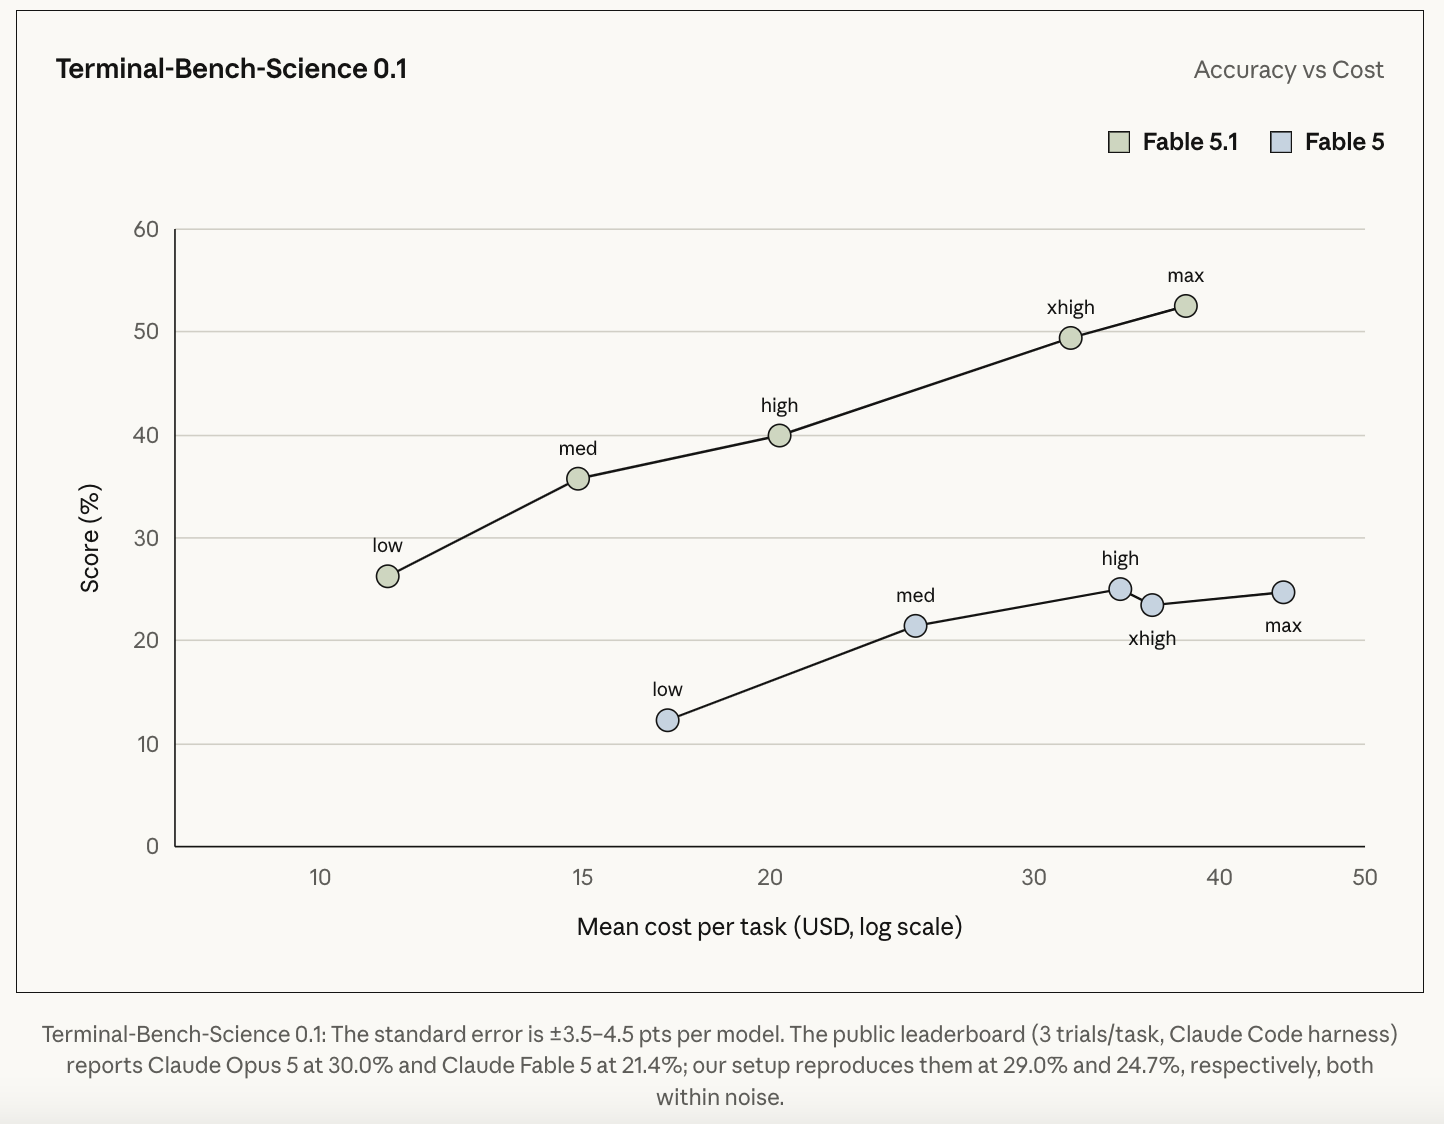
The numbers show a serious jump: terminal accuracy increased to 55.8% (from 42%), while performance in business process automation nearly doubled — 31.4% versus 17.1% for the previous version.
What are the practical benefits:
-
Autonomy in long tasks. The model can follow complex instructions for hours without constant human involvement. For example, during testing at Ramp, it worked continuously for 38 hours: running experiments, fixing data errors on its own, and delivering the finished result.
-
Working in the browser. In tests involving actions inside a browser, Fable 5.1 completed 82% of tasks. This will be useful for automated data collection, working with websites, and configuring complex scripts.
-
Finding issues in code. The model digs deeper into the logic: in tests by Millennium, it found the cause of a bug by analyzing someone else's code and logs that engineers had been investigating for several years.
-
Saving budget. Under average workloads, response quality became higher than in the previous version, while API usage costs became lower.
The model is already available on claude.ai, in the Claude Code tool, and through third-party platforms and aggregators.